
Maximize Your Ad Reach with FroggyAds Self-Serve DSP Platform
Launching a first programmatic campaign is less about finding a clever bid and more about avoiding avoidable waste. FroggyAds is a self-serve demand-side platform (DSP) built for performance marketers who want to buy traffic across push, native, display and pop formats through more than 750 supply-side platform (SSP) sources. Because the buying layer is self-managed, every decision about accounts, targeting, bids and pacing sits with the advertiser, which is both the main advantage and the main source of budget leaks when setup is rushed. This guide walks through the sequence that keeps spend readable from the first impression, and it shows where the platform's controls such as SmartCPC, Adscore screening and traffic-quality filters change the outcome. For a broader overview of how to optimize paid advertising across these formats, the same principles apply to every campaign you launch.

Setting Up a Self-Serve DSP Account Before the First Bid
The account stage determines whether your data will be trustworthy later. Before logging in, prepare the items that a self-serve workflow assumes you already have: a funded billing method, a clearly defined campaign goal, creative assets in the sizes each format requires, and a tracking endpoint that can receive conversion events. Source material for this platform notes a minimum deposit of $50 to start, so the practical budget floor is low, but a low floor is not a reason to skip the tracking test. A campaign that converts without an attributed event cannot be optimized, regardless of how cheap the traffic looks.
- Change one variable at a time so that any movement in results can be traced to a specific cause
- Cutting segments before they accumulate enough impressions removes candidates before the evidence exists, and it resets the learning process each time a bid or creative is edited too frequently
- Rotate creatives on a schedule tied to frequency data, and retire any version whose engagement falls sharply as its exposure rises
- Excluding the weakest sources after they clear the data threshold, and shifting budget toward the ones with verified conversions, is the most direct way to improve efficiency on a self-serve DSP
Structure matters as much as access. Account-level permissions govern who can change billing and settings, while advertiser-level and campaign-level objects govern what gets measured and optimized. Separate campaigns by geography, device or objective so that each one produces data that answers a single question. A push campaign aimed at mobile users in one region and a display campaign aimed at desktop users in another will produce mixed signals if they share a campaign, because the bidder learns from averages that describe neither audience. Naming conventions look like administration, but they make exported reports comparable across weeks, which is what you need when deciding whether a change worked.
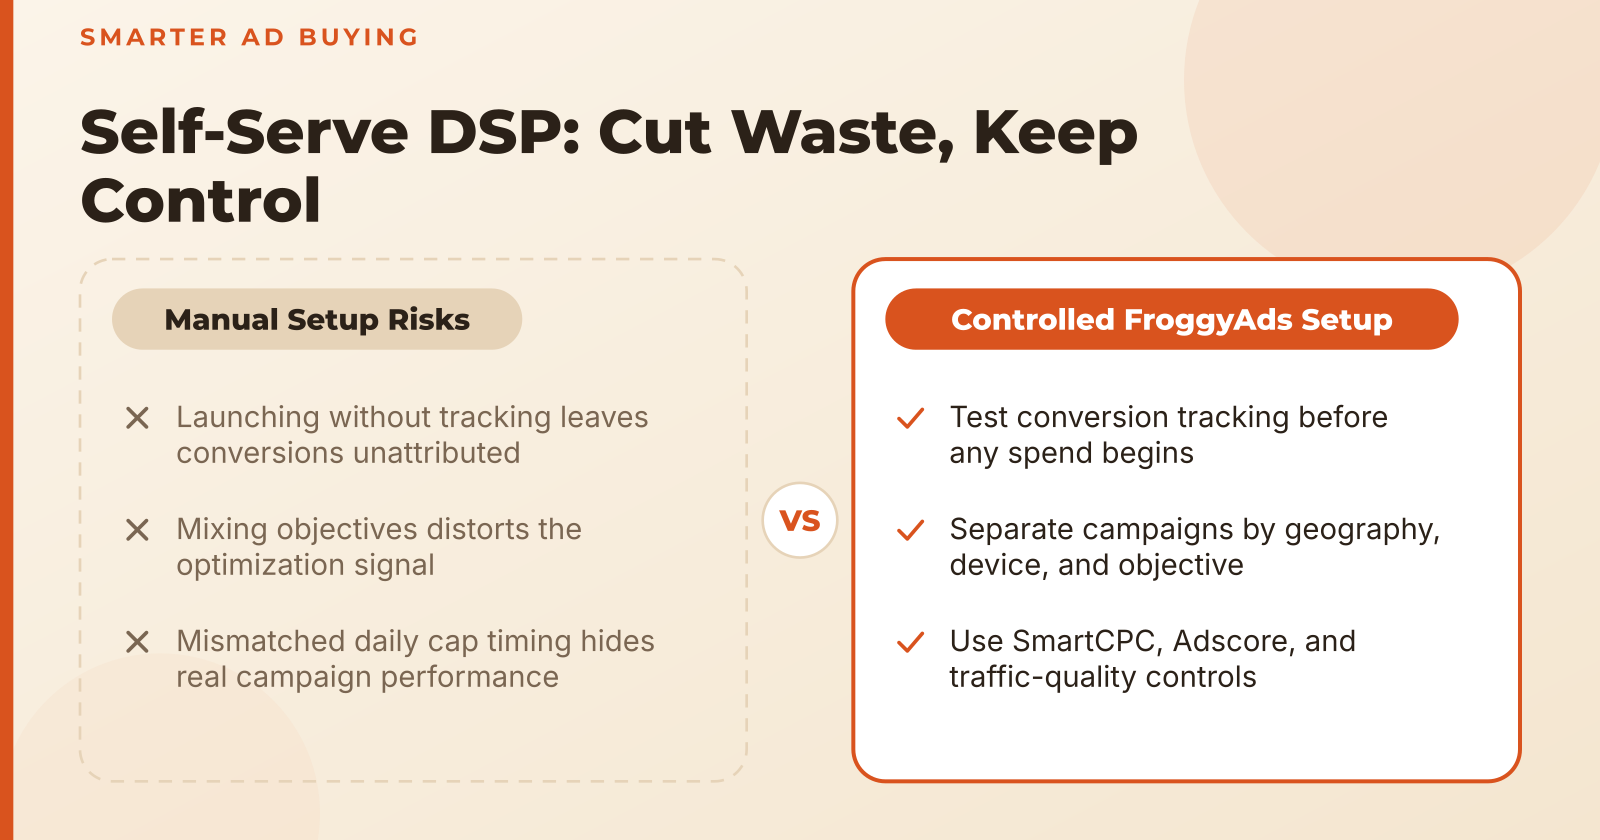
Three setup errors recur often enough to check for explicitly. The first is launching without a tracking test, which leaves conversions unattributed and turns every later decision into guesswork. The second is mixing objectives inside one campaign, such as traffic and sales, which distorts the optimization signal because the cheapest clicks are rarely the most valuable ones. The third is ignoring currency and time-zone settings. If the daily cap resets at a different hour than your reporting day, a campaign can appear to underdeliver or overspend when nothing is actually wrong with the bids.
Building Targeting and Audience Segments Step by Step
Targeting translates the campaign goal into filters the bidder can act on. The sound approach is to start broad and narrow only when data justifies it. Begin with geographic and device filters that match your offer, let the campaign collect a baseline, and then review which combinations deliver users who take the target action. Inventory type, whether web, app or another supported environment, should be treated as a controlled variable rather than a permanent choice. Testing one inventory type at a time makes it possible to see whether a result came from the audience or from the placement.
Quality controls work alongside targeting. Adscore screening filters invalid or low-quality sources before they reach your bids, which reduces the share of spend lost to traffic that cannot convert. Domain and app exclusion lists serve the same purpose at a granular level: once a placement has produced clicks without conversions over a meaningful sample, excluding it protects the remaining budget. Exclusions should be based on the performance of your own campaign rather than on general impressions of a publisher, because a source that underperforms for one offer can perform well for another.
Audience segments add precision but carry their own risks. First-party segments built from site behaviour or CRM data are usually the most relevant, and the recency window should match the length of your buying decision: a short-cycle offer can use a few days of activity, while a higher-consideration product needs a longer window. Lookalike seeds depend on two factors, the seed size and the relevance of the source. A small or loosely related seed produces a lookalike audience that drifts away from the people you want. Overreach appears when segments become so narrow that they starve the bidder and delivery stalls, or when too many filters stack together and push the effective cost per thousand impressions up while volume drops.
Setting Bids, Budgets, and Pacing
Bidding strategy should follow the amount of data you have. In early testing, manual CPM or CPC bidding gives predictable costs and makes it easier to read what each source is doing. Once conversion volume is sufficient, target CPA or ROAS modes let the system allocate spend toward the sources that convert. SmartCPC is designed to adjust bids automatically using performance signals, which is useful after you have enough conversions for those signals to mean something. Switching to automated goals with only a handful of conversions per week tends to produce erratic delivery, because the model has too little to learn from.
Budget structure controls how quickly the algorithm gathers evidence. Daily budgets suit ongoing campaigns, while lifetime budgets fit fixed-length promotions. Even pacing is the sensible default during testing because it spreads learning across the test period. Accelerated pacing belongs only to time-limited offers where delivery speed is the point. When testing several ad groups or creatives, split the budget with equal starting weights so that no variant wins simply because it received more impressions early.
Early delivery gives warning signs that deserve attention within hours rather than days. Spend concentrated on a single placement is the most common one, and it usually means that placement is the cheapest available rather than the best. A win rate close to zero indicates that bids are too low for the inventory you are targeting, so the campaign is not competing for impressions at all. Either outcome calls for a bid or filter adjustment before the budget is consumed by a narrow slice of traffic. Platforms such as optimize paid advertising tools with FroggyAds (ivanmsinyw) let teams set budgets, bidding rules and targeting on their own, which is why it helps to check how granular the reporting is before committing spend.
Reading the Metrics That Actually Matter
Impression-level diagnostics tell you whether the traffic is worth measuring at all. Viewability and invalid traffic rates act as quality gates: if they are poor, conversion data from that traffic will be unreliable regardless of how it looks. Frequency distribution reveals audience fatigue, since a small group seeing the same creative many times will generate falling engagement long before the campaign budget runs out. Win rate and average bid show how competitive your campaign is, which helps distinguish a creative problem from a bidding problem.
Conversion metrics should be judged against your margin, not against a generic benchmark. Cost per acquisition is useful only if you know the most you can pay per acquisition and still earn a return. The attribution window you choose changes reported results substantially: a short window undercounts delayed conversions, while a long window can credit the campaign for actions that would have happened anyway. When several touchpoints contribute to a sale, compare assisted and last-touch conversions so that you do not cut a placement that is quietly starting journeys that other channels finish.
Decision rules keep optimization disciplined. Set a minimum data threshold before pausing any placement or segment, expressed as impressions or conversions rather than as a number of hours. Schedule review points, such as every three to five days, instead of reacting to hourly fluctuations, which are often just normal variance in auctions. Resist the urge to intervene at every dip.
Common Optimization Errors and How to Avoid Them
Over-optimizing early is the error that most often wastes budget on a new campaign. The practical rule is to let a test run to its threshold, then decide, and to make only one change between review points so the learning period is not constantly restarted.
Creative and frequency mismanagement is the second recurring problem. Running a single creative until its performance decays means the campaign spends the final part of its budget on an audience that has already seen the message repeatedly. Keeping at least two or three variants live at once gives the platform something to compare, and it gives you a clean reading of which message holds attention.
Ignoring source-level reporting is the third error. The platform's reporting shows which of the 750-plus SSP sources contribute conversions and which only contribute clicks. Advertisers who review only campaign totals miss this detail entirely.
The most reliable campaigns on a self-serve platform are the ones where each change is made for a stated reason, against a stated threshold, and with enough data behind it to be read.
Launching well on FroggyAds comes down to sequence: confirm the account and tracking first, build targeting from broad filters toward narrower ones, match the bidding strategy to conversion volume, and judge every placement by its own measured results. The platform's SmartCPC bidding, Adscore-screened traffic and source-level reporting give a performance marketer the means to act on those results, but they only pay off when the advertiser applies discipline to each stage. For a first campaign, the most useful outcome is not a single strong week but a dataset clean enough to explain why the campaign worked, which is what makes the second campaign cheaper to run than the first. Once that habit is established, the same routine scales to new formats, new geographies and larger budgets without losing control of where the money goes. If you are ready to FroggyAds: Self-Serve DSP Ad Network and test this process on your own offer, start with a small budget, a single clear objective and a tracking check, and let the first two review cycles tell you what to change next.